 audio-to-audio
Personaplex
fal-ai/personaplexPersonaPlex is a real-time, full-duplex speech-to-speech conversational model that enables persona control through text-based role prompts and audio-based voice conditioning.
Browse the public fal model directory. Models become callable through Kaista Cloud only after supply, pricing, and compatibility review.
audio-to-audiofal-ai/personaplexPersonaPlex is a real-time, full-duplex speech-to-speech conversational model that enables persona control through text-based role prompts and audio-based voice conditioning.
 image-to-image
fal-ai/qwen-image-edit-plus-lora-gallery/lighting-restorationRemoves harsh shadows and light spots from images, replacing them with soft, even, natural-looking illumination.
 training
fal-ai/ltx23-trainer-v2/i2vFine-tune LTX 2.3 to animate a starting image — supply a still plus a prompt at inference and the model generates a video that begins from that frame.
 vision
fal-ai/sam-3/image/embedSAM 3 is a unified foundation model for promptable segmentation in images and videos. It can detect, segment, and track objects using text or visual prompts such as points, boxes, and masks.
 video-to-video
fal-ai/ltx-2.3-quality/hdrGenerate HDR from reference video using LTX-2.3
 text-to-image
fal-ai/ideogram/v2aGenerate high-quality images, posters, and logos with Ideogram V2A. Features exceptional typography handling and realistic outputs optimized for commercial and creative use.
 image-to-video
fal-ai/pixverse/v5.6/transitionUse the latest pixverse v5.6 model to turn your texts and images into amazing videos.
 training
fal-ai/wan-22-image-trainerWan 2.2 text to image LoRA trainer. Fine-tune Wan 2.2 for subjects and styles with unprecedented detail.
 image-to-image
fal-ai/vidu/reference-to-imageVidu Reference-to-Image creates images by using a reference images and combining them with a prompt.
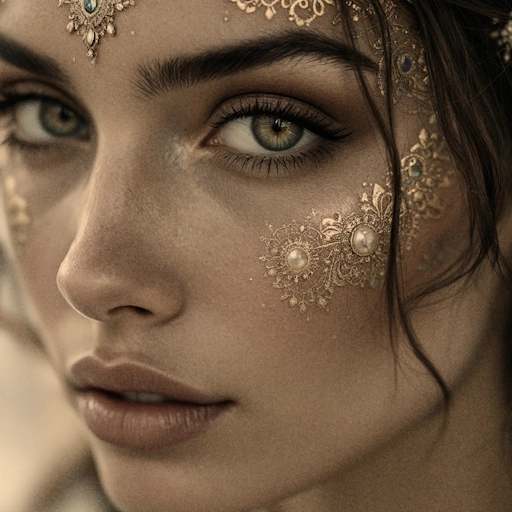 image-to-image
fal-ai/post-processing/grainApply film grain effect with different styles (modern, analog, kodak, fuji, cinematic, newspaper) and customizable intensity and scale
 image-to-image
fal-ai/chrono-edit-loraLoRA endpoint for the Chrono Edit model.
 audio-to-audio
fal-ai/stable-audio-3/small/music/base/audio-to-audioStable Audio 3 Small Music Base audio-to-audio is the foundational 459 million parameter checkpoint that transforms input music into new variations up to 2 minutes guided by text prompts.
 video-to-video
fal-ai/thinksound/audioGenerate realistic audio from a video with an optional text prompt
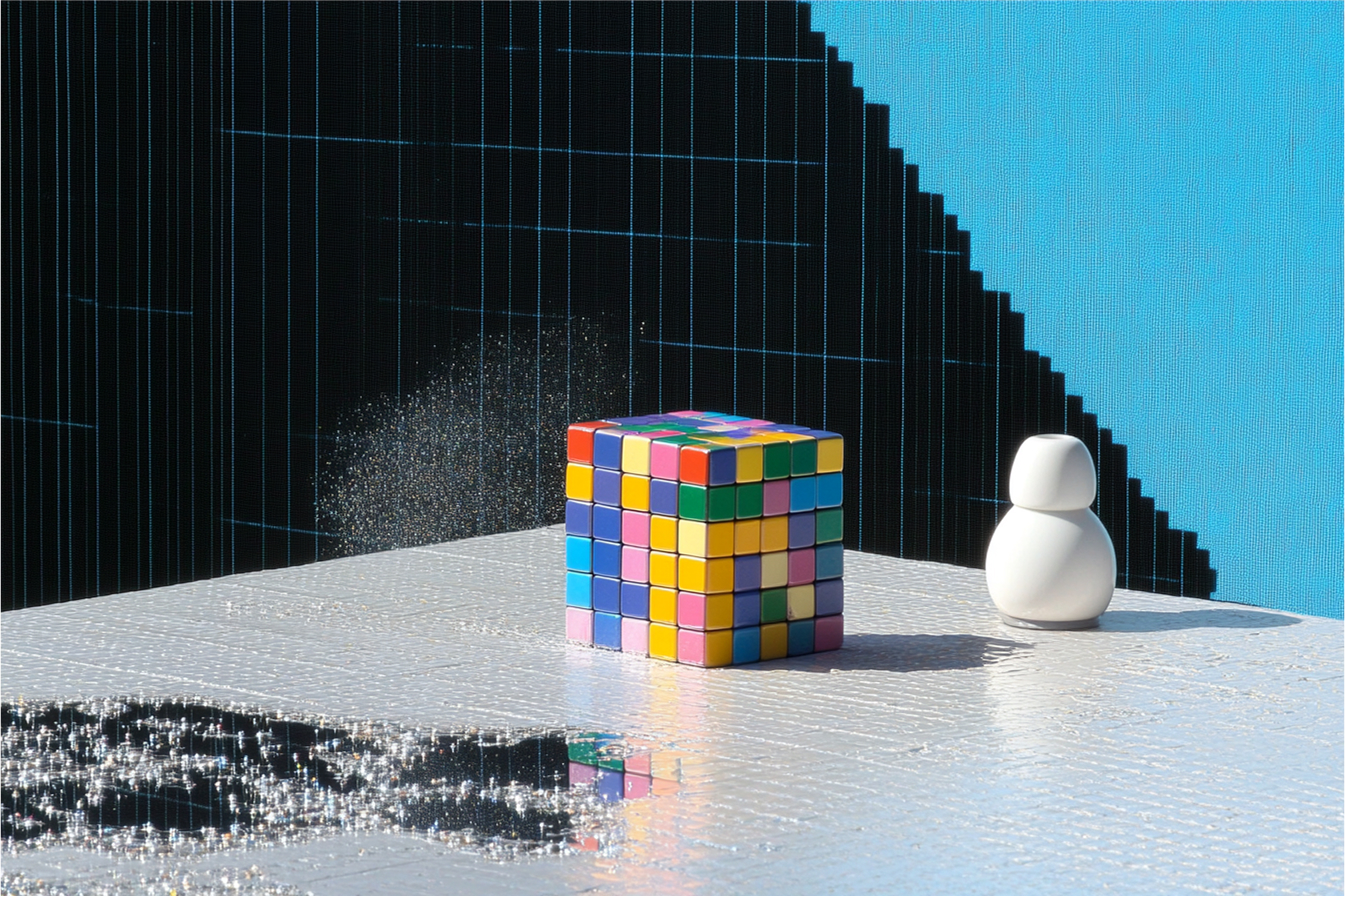 image-to-image
fal-ai/object-removal/bboxRemoves box-selected objects and their visual effects, seamlessly reconstructing the scene with contextually appropriate content.
 audio-to-video
veed/avatars/audio-to-videoGenerate high-quality videos with UGC-like avatars from audio
 text-to-image
fal-ai/flux-2-lora-gallery/digital-comic-artTransforms images into comic book style
 video-to-video
blackforestlabs/flux-3/extend-video/draftFLUX.3 is Black Forest Labs' frontier audio/video model. Generate fast, low-cost draft previews that continue an existing clip, with a reusable draft cache for full-quality enhancement.
 audio-to-audio
fal-ai/stable-audio-3/medium/base/audio-inpaintingStable Audio 3 Medium Base audio inpainting is the foundational 1.4 billion parameter checkpoint for editing or filling selected stereo audio segments guided by text prompts.
 text-to-image
rundiffusion-fal/juggernaut-flux/baseJuggernaut Base Flux by RunDiffusion is a drop-in replacement for Flux [Dev] that delivers sharper details, richer colors, and enhanced realism, while instantly boosting LoRAs and LyCORIS with full compatibility.
 audio-to-video
fal-ai/echomimic-v3EchoMimic V3 generates a talking avatar model from a picture, audio and text prompt.
 video-to-video
fal-ai/ltx-2.3-quality/reference-video-to-video/loraGenerate high-quality video with audio from reference video, text and images using LTX-2.3 and custom LoRA
 image-to-image
bria/fibo-edit/reseasonTransform the season or weather of an image - summer to winter, sunny to rainy - with realistic atmosphere and lighting. Trained exclusively on licensed data for risk-free commercial use.
 video-to-video
fal-ai/ltx-2.3-quality/clean-plateRemove character from your video using Ltx 2.3
 image-to-image
fal-ai/qwen-image-edit-plus-lora-gallery/face-to-full-portraitGenerate full portrait from a cropped face photo
 image-to-image
fal-ai/image-preprocessors/samSegment Anything Model (SAM) preprocessor.
 text-to-json
bria/fibo-lite/generate/structured_promptConvert plain text into Fibo-Lite's transparent JSON-structured prompts - Bria's unique controllability layer that no closed model offers. Built for agentic and enterprise workflows.
 text-to-image
fal-ai/bria/text-to-image/fastBria's Text-to-Image model with perfect harmony of latency and quality. Trained exclusively on licensed data for safe and risk-free commercial use. Available also as source code and weights. For access to weights: https://bria.ai/contact-us
 image-to-image
fal-ai/lora/inpaintRun Any Stable Diffusion model with customizable LoRA weights.